Tag: model-tiering
Posts with tag model-tiering
I Was Wrong About Haiku
I ran one model for everything and blamed the plan when usage climbed. The fix was splitting the work, and the saving turned out to have nothing to do with token price.
Aug 27, 20265 min read
Read more
Claude Fable 5 Dropped. My Pipeline Isn't Getting It (Yet)
Claude Fable 5 launched this week — record benchmarks, twice the price of Opus. My production pipeline's config hasn't changed, and that's not neglect. Benchmarks measure raw models. Pipelines run calibrated ones.
Jun 11, 20266 min read
Read more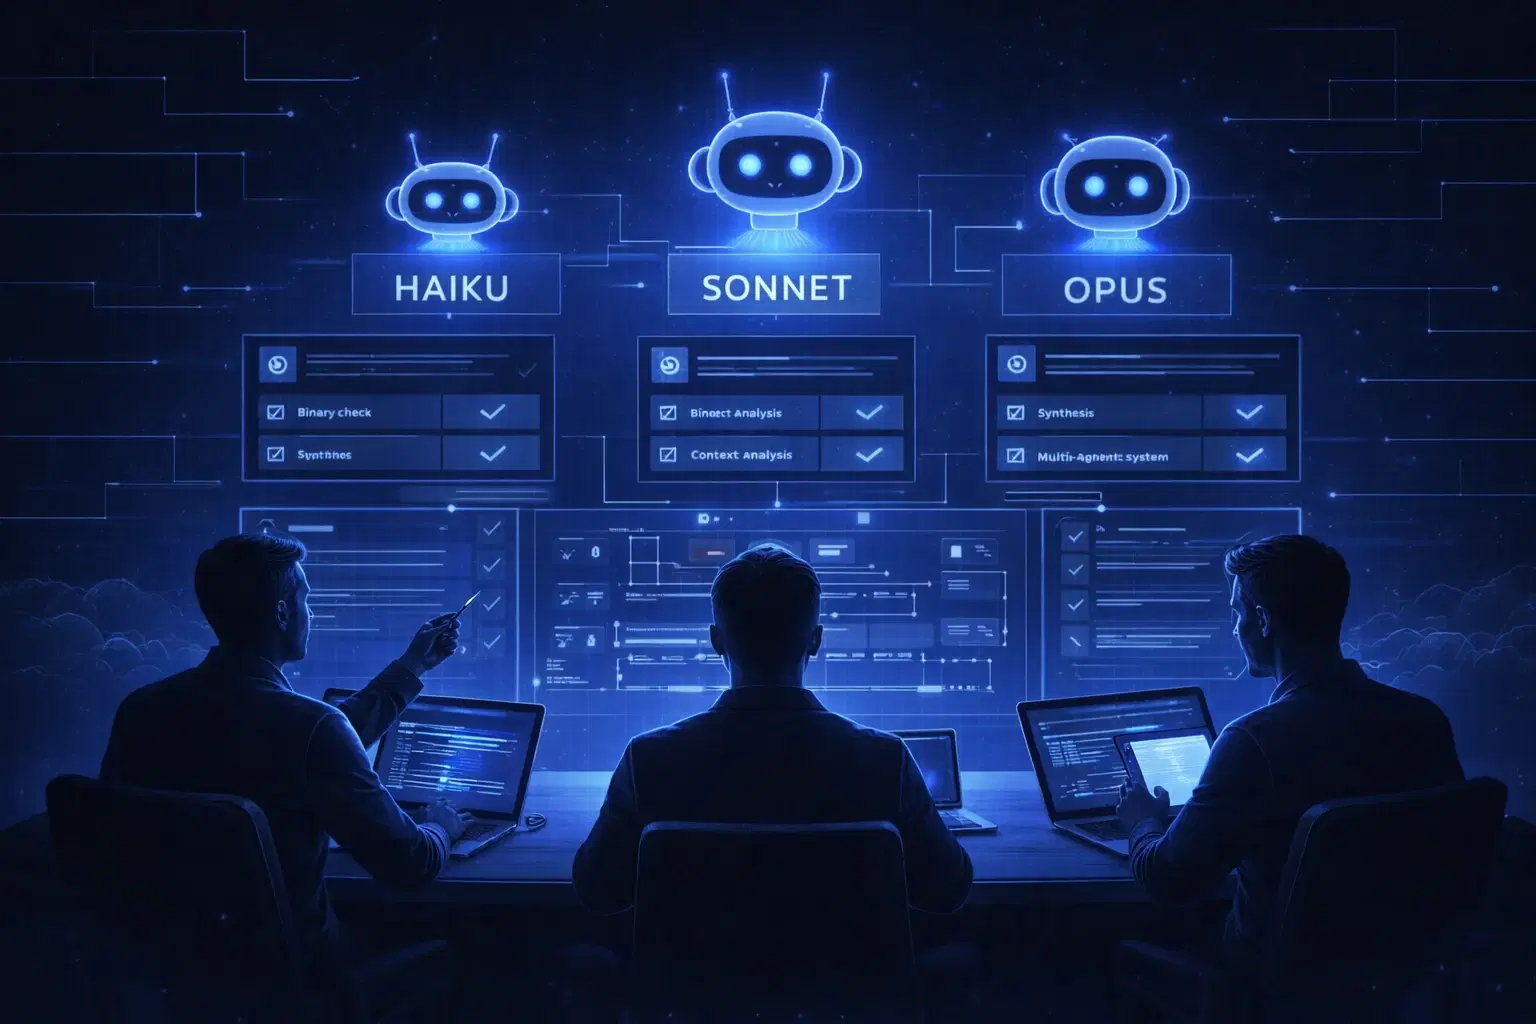
Why I don't use one Opus for everything — model tiering in a multi-agent system
Running the most powerful model on every task is wasteful and slow. Here is how I split work across Haiku, Sonnet, and Opus — and why it matters at scale.
Apr 7, 20264 min read
Read more