I Was Wrong About Haiku
I ran one model for everything and blamed the plan when usage climbed. The fix was splitting the work, and the saving turned out to have nothing to do with token price.
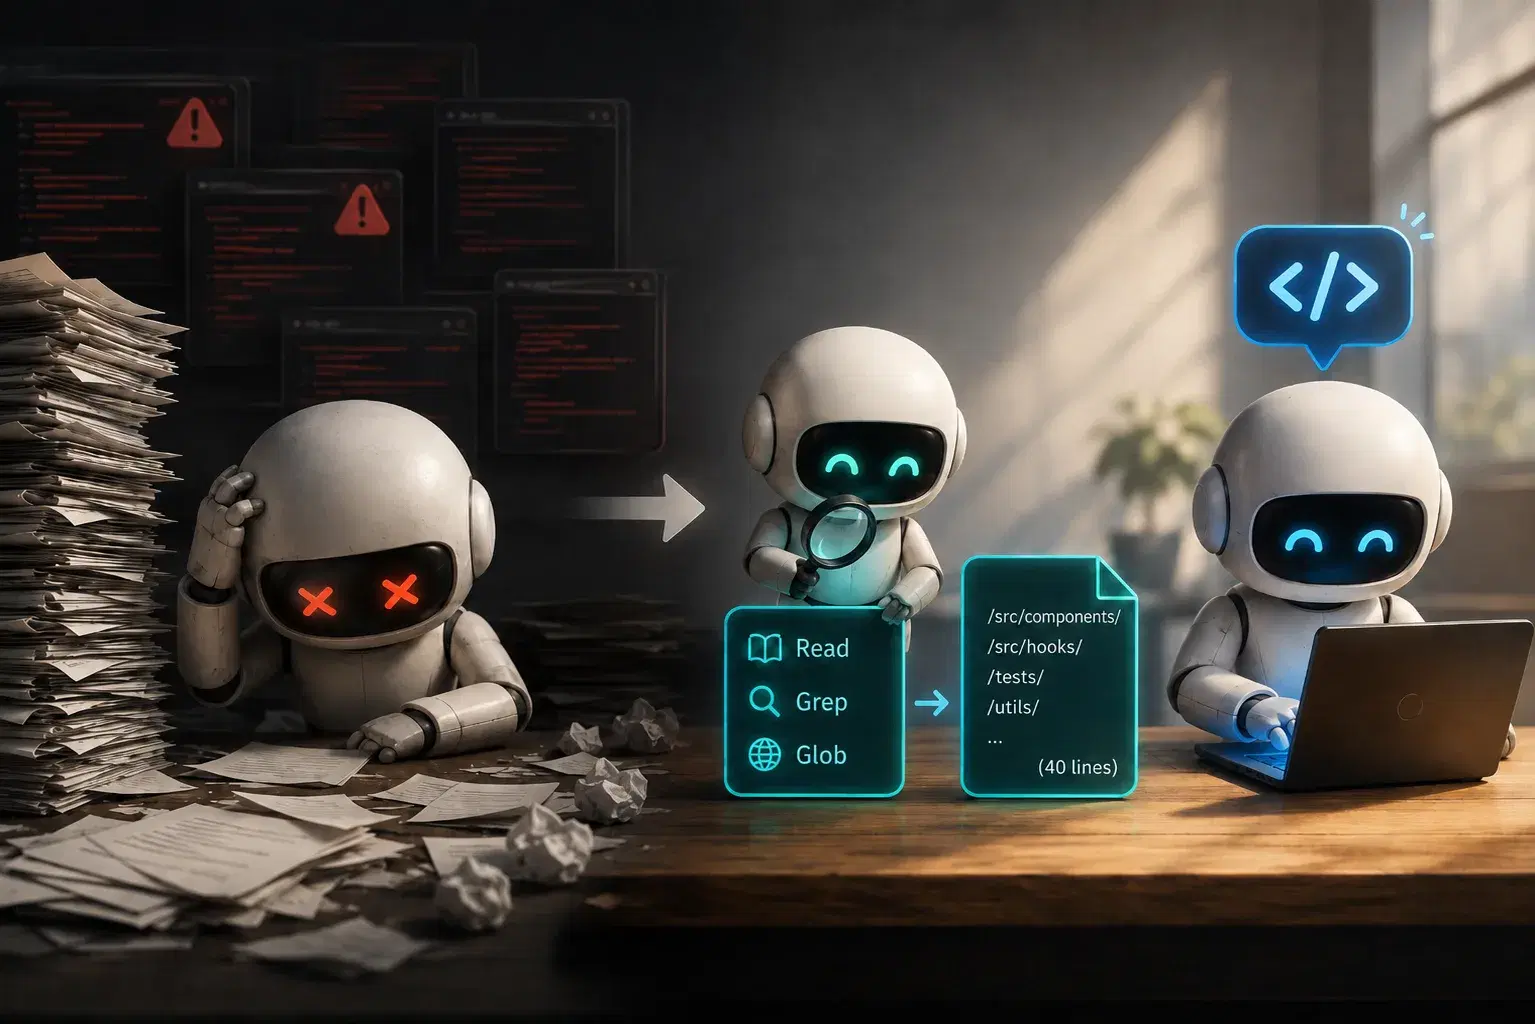
I used to repeat that Haiku is useless.
I had a reason. Everything I threw at it came back shallow, so I stopped throwing things at it. One model for everything, all day. Then my usage on the Pro plan started climbing and I did what most people do at that point: I assumed the plan was the problem, looked at the price of the next tier, and decided I did not want to pay it.
That decision turned out to be the useful one, but not for the reason I expected. Refusing to upgrade forced me to find out whether the ceiling was the plan or my setup.
The thing I was already doing at work
I had this solved in a client project and had not noticed I was solving it.
Most of a task is not the hard part. Before anything gets written, someone has to answer a set of boring questions. Which files does this touch. How are similar things named in this corner of the codebase. Is there an existing implementation worth copying. Where do the tests live and what framework are they in.
That is search and summarisation. It requires no judgment. It is also the phase that quietly eats the most context, because doing it properly means reading a lot of files that will turn out to be irrelevant.
So it should not be running in the same place as the part that makes decisions.
The split
The exploration phase became its own subagent. Two constraints matter more than which model runs it.
Three tools, all read-only. Read, Grep, Glob. This is not a rule the
agent is asked to follow. It is the complete set of things it can do. It cannot
edit a file because it has no tool that edits files. There is a difference
between an agent that has been told not to write and an agent that has no
writing available, and the difference shows up on the day the instruction gets
ignored.
A hard budget: forty lines, paths not code. The explorer returns locations, not excerpts. It is told explicitly not to quote what it found.
That second constraint is the one that pays.
The saving is not where I thought it was
My first explanation was the obvious one. Cheaper model, cheaper tokens, smaller bill. That explanation is wrong, or at least it is the least interesting part of what happens.
What actually changes is that the raw material never enters the main context. Sonnet receives a forty-line brief describing where things are. It does not receive the eleven files the explorer opened to write that brief. The expensive context stays clean, which means the session survives more real changes before it degrades.
The model assignment follows from the shape of the task, not the other way round. Haiku is there because "find where this lives" is a retrieval job, and retrieval jobs do not need the model that will later decide how to restructure a component. If the pricing were identical I would still split it.
There is a second reason the split is safe, and it took me a while to see it. The cost of a bad exploration is low. If the explorer misses a file, the main loop reads it during the planning phase and moves on. The failure mode is one extra read, not a wrong change. That asymmetry is what makes it reasonable to delegate the phase at all.
What I can and cannot claim
I want to be precise here, because this is where posts like this usually overreach.
What I can say is that my sessions last noticeably longer and I get through more actual changes before hitting a wall. That is an observation from daily work over several weeks, not a measurement. I did not run the same task twice under both configurations and compare token counts. I do not have a controlled before and after, and the usage graphs I could show you would not prove what I would want them to prove.
So treat this as a report from someone who changed one thing and liked the result, not as a benchmark. If you try it and it does nothing for you, that is a real data point and I would rather hear it than not.
Where it breaks
The forty-line budget is tuned for a single-app repository. On a large monorepo it is too tight, and what you get back is a partial picture delivered with complete confidence, which is worse than an obviously incomplete one. Raise the number before concluding the approach does not work.
The rules I pair this with tell the agent to copy local conventions even when it disagrees with them. In a codebase you are actively trying to move away from, that is the wrong instruction and it will cement things you were trying to remove.
And the conventions the explorer looks for are frontend-shaped. Hooks, composition, import style. On a different stack that section needs rewriting rather than copying.
The setup
The whole thing is three files: the explorer subagent, a skill holding the rules that apply to every change, and a slash command that runs the five phases in order. It is on GitHub under MIT:
github.com/ivansportfolio/claude-code-workflow
Copy the .claude/ directory into a project and it works, assuming your
CLAUDE.md actually lists your lint, typecheck and test commands.
The question was never whether the small model is good enough. It was how much of my day is spent finding out where things are, and the honest answer is: most of the beginning of every task.
Was this helpful?