My Model Had the Data. Then It Told the User My Database Schema.
My Model Had the Data. Then It Told the User My Database Schema.
I asked my dashboard for the cheapest listing.
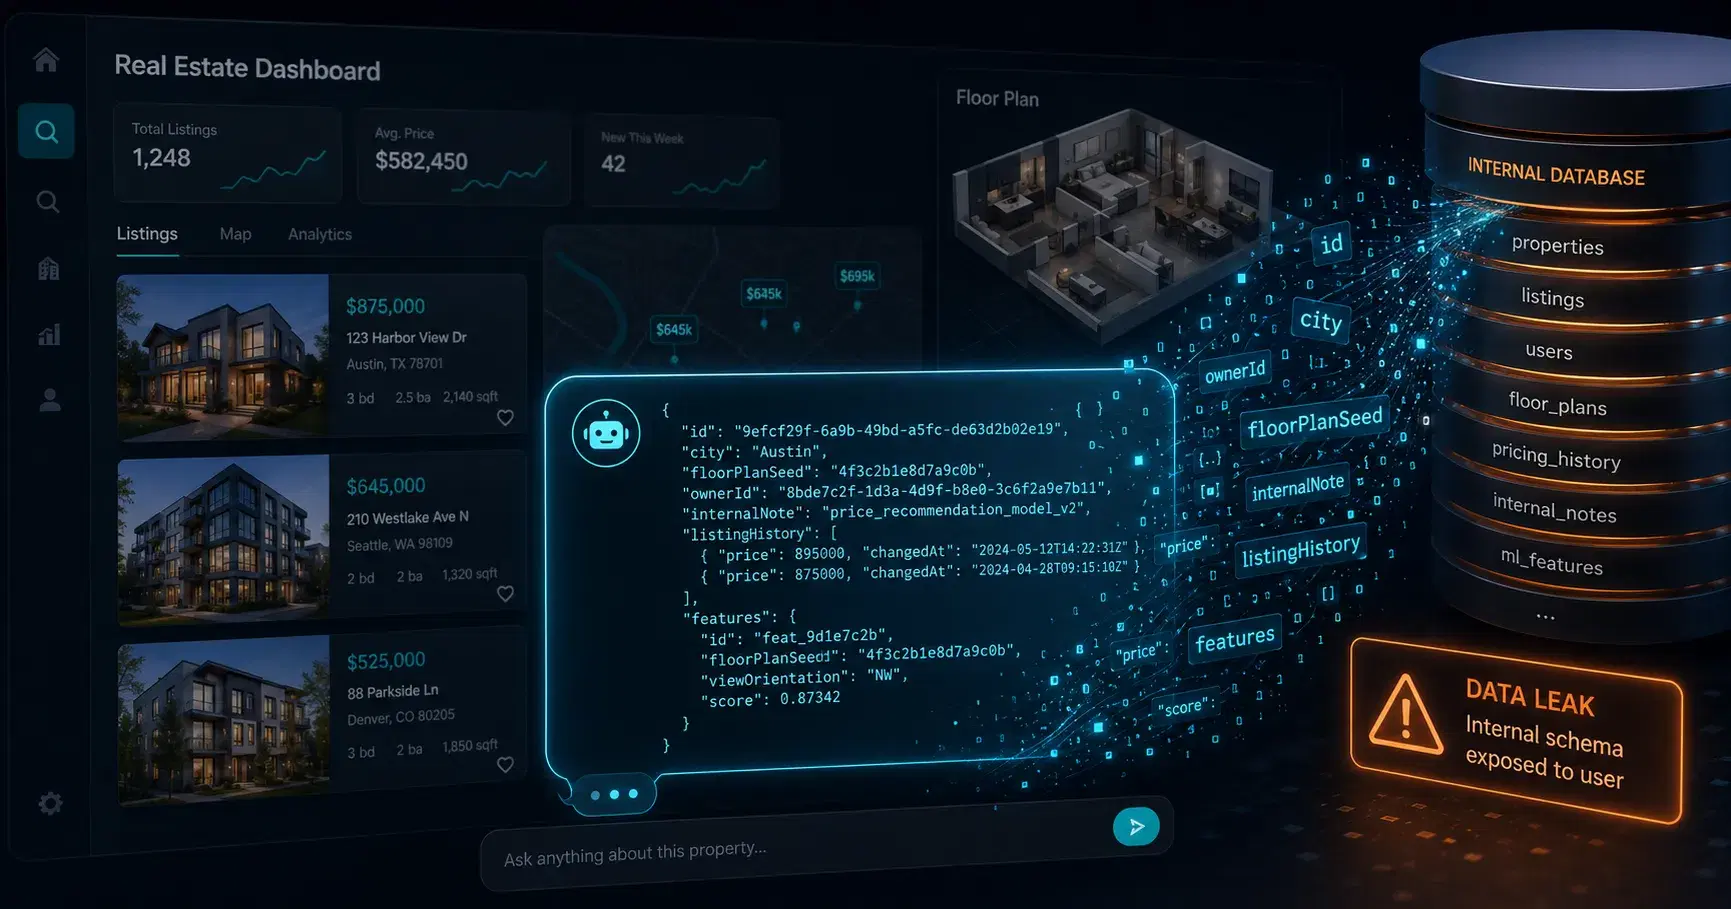
It answered with this:
Proszę sprecyzuj, co chciałbyś zrobić. Czy chcesz zobaczyć ofertę z identyfikatorem '9efcf29f-6a9b-49bd-a5fc-de63d2b02e19', porównać oferty, czy może poszukać nieruchomości w Marki?
Not a price. Not an address. A UUID, quoted back at me in a chat bubble, in a sentence that also asks me to pick from three options I never mentioned.
Part 1 of this series ended with a promise: AI on top of data only works when the data has a model. So I fixed the data, wrote about it, and moved on to the fun part.
The data was fine this time. That is not where it broke.
What I built
Same project as before. High Water Mark, a small real estate dashboard, React and TypeScript, 50 generated listings, filters, a map of Poland, a 3D floor plan per property.
The new piece is a chat panel on the right. Ollama running locally, gemma3:4b, with the listings passed in as context. You type what you want in plain Polish, the assistant is supposed to translate that into filters and apply them.
Nothing exotic. This is roughly what everyone is bolting onto their product right now.
The part that works
Worth saying clearly, because the screenshot above makes it look like nothing works.
Retrieval is fine. The model finds listings. When I type "Mieszkanie 77 m² - Marki" it correctly narrows down to that one property, understands it is a 77 square meter flat in Marki, and answers about it. It knows the identifier of the record it is talking about.
That last sentence is the problem.
The bug
Here is the shape of what I was sending, simplified:
const context = JSON.stringify(listings);

const messages = [
  { role: 'system', content: `Oferty: ${context}` },
  { role: 'user', content: userInput },
];
Two lines. Looks harmless. Every tutorial on the internet has some version of it.
But listings is my internal domain object. It has everything the app needs,
because that is what domain objects are for:
type Listing = {
  id: string; // uuid, internal
  title: string;
  city: string;
  district: string;
  voivodeship: string;
  type: PropertyType;
  area: number;
  rooms: number;
  price: number;
  pricePerSqm: number;
  status: ListingStatus;
  floorPlanSeed: number; // internal, drives the 3D generator
  createdAt: string;
  // ...
};
I handed all of it to the model and told it to be helpful.
So it was. It used id when it needed to refer to a record, because that is
what id is for. It quoted the field name city back at me when it wanted me
to change a filter, because the field is called city and the model had no
other name for it.
The model did not leak anything. It repeated what I gave it. There is no bug in gemma here. The bug is that I never decided what the model was allowed to know.
Why this is not a cosmetic problem
On my project this is embarrassing at worst. Mock data, a UUID, a field name. Ugly output, nothing more.
Now do the same thing on a real product.
Your Listing type does not stop at price and area. It has internalNotes. It
has ownerPhone. It has commissionRate, acquisitionCost,
sellerMotivation, minimumAcceptedPrice. Somebody added a flags array two
sprints ago and nobody remembers what is in it.
Then somebody writes JSON.stringify(listings) into a system prompt, because
that is the fastest way to get the demo working, and now the minimum accepted
price is one clumsy question away from the buyer.
Nothing in your stack will stop this. TypeScript will not, because the type is correct. Your linter will not. Code review probably will not, because the diff is two lines and both of them look like plumbing.
And it will not fail loudly. It will work beautifully, right up until it says something it should not.
The fix
The instinct is to strip the bad fields. Delete id before sending, delete
floorPlanSeed, move on.
That is a blocklist, and blocklists rot. The next person to add a field to
Listing does not know your prompt exists. Six months later there is a new
sensitive column and nobody updated the delete list.
So instead: an explicit type for what the model gets, and a mapper that builds it.
// Everything the model is allowed to see. Nothing else exists for it.
type ListingForModel = {
  ref: string; // short, human-safe handle, not the uuid
  title: string;
  city: string;
  type: string;
  area: number;
  rooms: number;
  price: number;
  pricePerSqm: number;
  status: string;
};

function toModelView(listing: Listing, index: number): ListingForModel {
  return {
    ref: `#${index + 1}`,
    title: listing.title,
    city: listing.city,
    type: labelFor(listing.type),
    area: listing.area,
    rooms: listing.rooms,
    price: listing.price,
    pricePerSqm: listing.pricePerSqm,
    status: labelFor(listing.status),
  };
}
Three things changed, and only one of them is about security.
The allowlist direction. New fields on Listing do not reach the model by
default. They reach it when somebody explicitly adds them to ListingForModel,
which is a small file that exists for exactly that decision. Adding a field is
now a choice instead of an accident.
The ref field. The model still needs to point at a specific record, so it
gets a handle. Just not the primary key. #7 is something a human can read out
loud. The UUID stays on my side, in a lookup table that maps refs back to real
ids.
Labels instead of enum values. labelFor(status) turns SOLD into
Sprzedane. The model repeats whatever vocabulary you give it, so give it the
vocabulary your users already see in the interface. If the model says a word the
UI never says, you built two products.
The last one sounds like a detail. It is the whole idea in miniature: the model's context is user-facing copy, not a data dump. Write it like copy.
The pattern underneath
Part 1 was about a data generator that rolled every field independently, so each value looked plausible and the relationships between them were nonsense.
This is the same mistake, one floor up.
I fixed the layer I was looking at and never asked what sat above it. I was so focused on whether the data had a model that I never asked what the data was allowed to say. And when the model answered, it answered in the vocabulary of my database, because that was the only vocabulary I had ever given it.
Every layer needs somebody to ask what it is allowed to expose. Storage to API. API to client. Client to user. We have decades of habit around those. DTOs, serializers, view models, response schemas. Nobody ships a REST endpoint that returns the raw row anymore.
Then LLMs arrived and we all went back to JSON.stringify(everything) in a
single afternoon.
There is a version of this in my last post too, about agent config files that nobody reviews. Same shape. A surface that carries real consequences and sits outside the places where we habitually look.
What is still broken
I am not fixing everything before writing about it, same as last time.
The assistant still does not do anything. Every answer is a request for clarification. You give the clarification, you get another request. I said "nie" to a question about preferences and it responded by offering me three new options. The filters at the top of the dashboard never move, no matter what the chat says it is doing.
So the assistant currently understands you and then does nothing about it. Which is a more interesting failure than a leaking UUID, and it is what Part 3 is about.
The uncomfortable summary of this one: the model was never the problem. My context was.
Part 1: My AI-built dashboard looked great. Then I read my own data.
Was this helpful?